November 5, 2025
|
5 min read

Updated: October 24, 2026
Published: June 10, 2026
Blazingly fast way to build, track and deploy your models!
Claude Fable 5.1 is the current version of Anthropic's Mythos-class Fable model, built for long-running coding, research, knowledge work, and agentic workflows. It supports a 1-million-token context window and 128K maximum output, with $10/M input and $50/M output token pricing. Anthropic says Fable 5.1 costs about 25% less than Fable 5 for typical workloads because of cheaper cache reads.
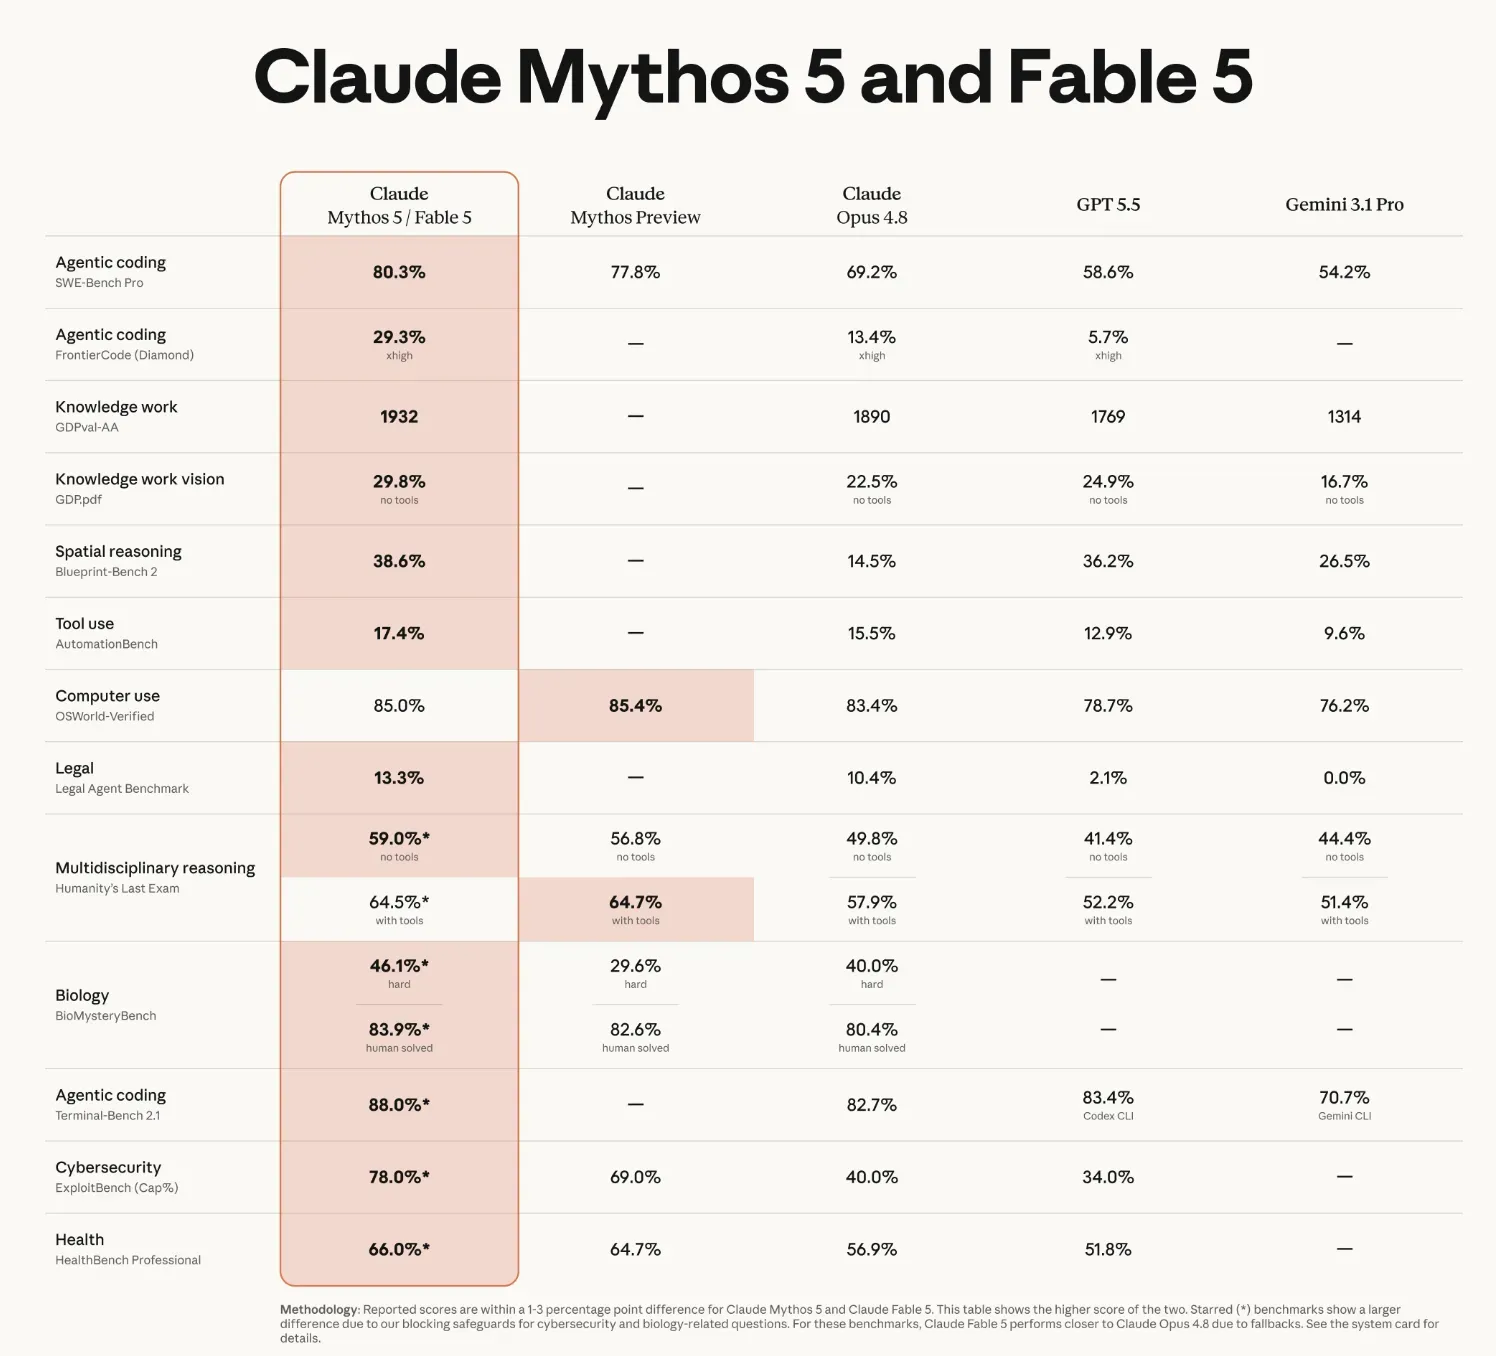
If you've spent the last year watching models inch forward half a point at a time on a benchmark, Fable 5 is a jolt. It posts 80.3% on SWE-Bench Pro while the next-best model sits 11 points behind. It finished a migration in a 50-million-line codebase in a day. And Andrej Karpathy called it "a major-version-bump-deserving step change forward." This guide covers what it is, how it benchmarks, what it costs, and exactly how to put it into production, with every figure traced back to Anthropic's launch materials.
Claude Fable 5 is Anthropic’s model designed for complex, long-running tasks that require more than a quick answer. It was built for work such as advanced coding, deep research, large-scale analysis, and other agentic tasks where Claude may need to reason through multiple steps and use tools over an extended workflow.
Anthropic positioned Fable 5 as its first Mythos-class model for general use. The idea was simple: the more complicated and time-consuming a task becomes, the more useful a model designed for long-horizon work can be. For a simple question, you may not notice a major difference. For a task involving dozens of steps, large amounts of information, or sustained tool use, the difference becomes more relevant.
However, Claude Fable 5 is no longer the latest version. Anthropic released Claude Fable 5.1 in September 2026, bringing improvements to long-running agentic coding, multi-step research, and work involving documents, spreadsheets, and presentations. Fable 5.1 also supports a 1-million-token context window and up to 128,000 output tokens.
There is also a close connection between Fable and Anthropic’s Mythos models. Fable 5.1 and Mythos 5.1 share the same underlying model, but they are offered with different safeguards. Fable is the version intended for general availability, while Mythos is restricted to vetted organisations working on areas such as cybersecurity and life sciences.
So, when you see Claude Fable 5 mentioned today, it refers to the model that introduced this model family. If you are looking for the current version, Claude Fable 5.1 is the relevant model to explore.
Here's the complete benchmark set Anthropic published at launch. A few things to read carefully:
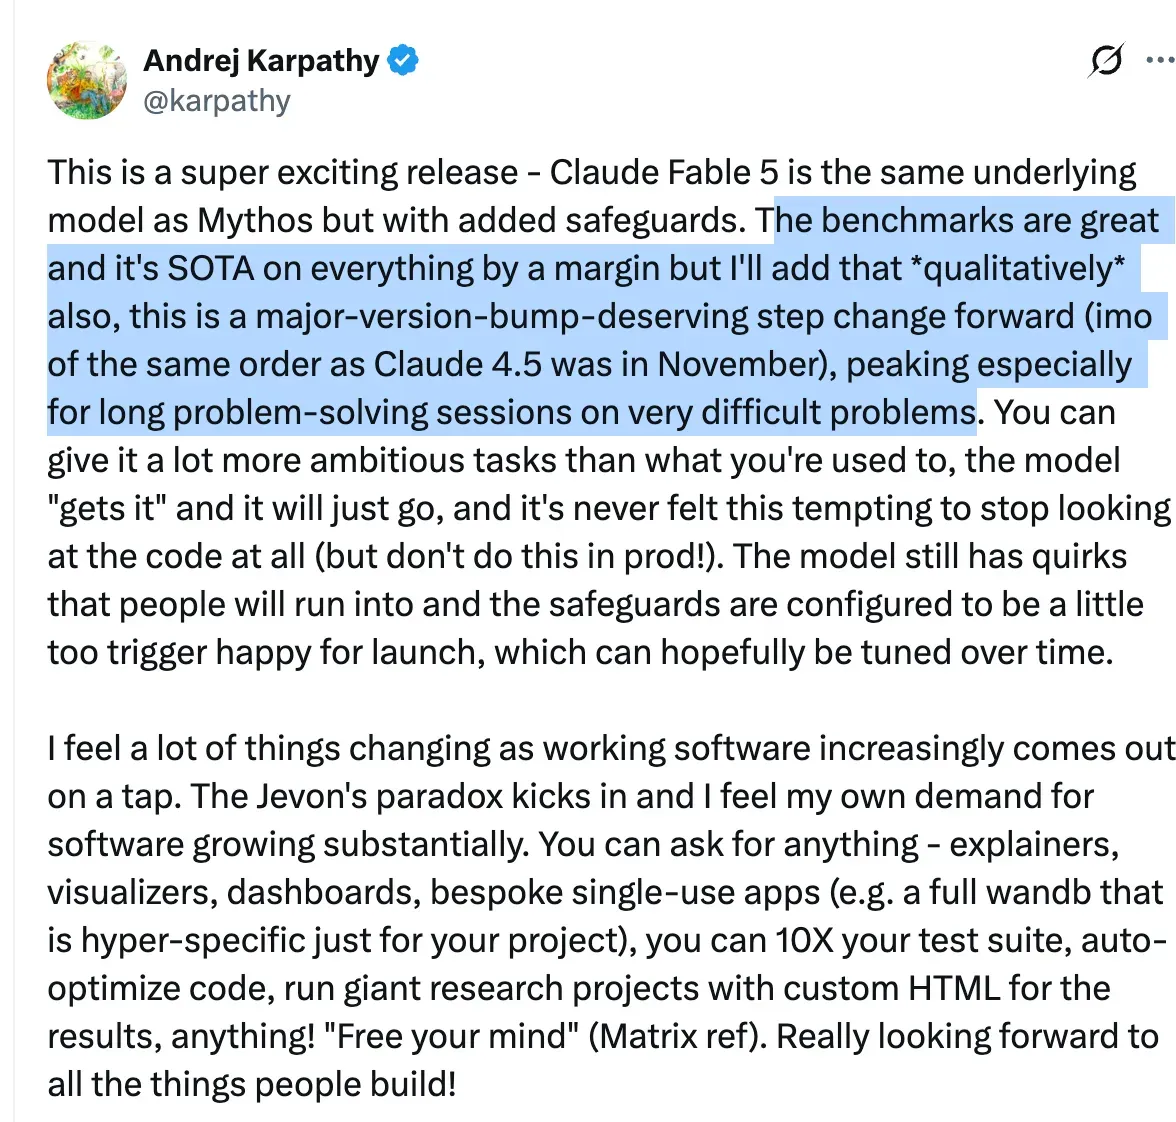
Andrej Karpathy's launch-day reaction captured the mood, and notably backed up the "step change" framing with a qualitative read, not just the scores:
Here is the difference between Claude Fable 5 vs Opus 4.8:
Claude Fable 5 is built for complex, long-running tasks, but it is not the right choice for every workload. Its biggest limitations are its higher cost, potentially high token usage, and safety restrictions that can affect how it handles certain requests.
Because Mythos-class capabilities carry real misuse risk, Fable 5 ships with classifiers covering cybersecurity, biology/chemistry, and distillation. When a request trips one, it's automatically answered by Claude Opus 4.8 instead, and the user is told. Anthropic reports this happens in fewer than 5% of sessions; over 95% of Fable sessions involve no fallback at all.
This is also exactly why the starred benchmark rows above matter: on those cyber/bio tasks, the published high score is Mythos 5's, while Fable 5, with safeguards active, performs closer to Opus 4.8.
What you need to know as a developer:
A gateway helps here: you can log which requests fell back, route them consistently, and keep the behavior uniform across your app.
Claude Fable 5.1 is priced as a premium model, with a higher per-token cost than Anthropic's lower-priced models. The current standard pricing is $10 per million input tokens and $50 per million output tokens.
The standard input and output rates apply when Claude processes tokens normally. Prompt caching is priced separately. Cache writes cost more than standard input tokens, but subsequent cache reads are much cheaper at $0.25 per million tokens. This can make caching useful when you repeatedly send the same large prompts, system instructions, or context.
Fable 5.1 also supports Anthropic's Batch API, which provides a 50% discount on input and output token pricing for eligible asynchronous workloads.
The headline price does not necessarily represent the final cost of every task. A long-running agentic workflow can generate a large number of input and output tokens, while effective caching can reduce the cost of repeatedly processing the same context. Your actual spend therefore depends on the length of the prompts, the amount of output generated, how often context is reused, and whether you use standard or batch processing.
If you are comparing prices with older references to Claude Fable 5, keep in mind that Fable 5.1 is the current version. The pricing table should therefore use Fable 5.1 rather than presenting launch-period Fable 5 pricing as current.
Fable 5 is available today on:
Grab an API key from the Claude Console and call the model with the string claude-fable-5. Anthropic's quickstart walks through authentication and your first request: see the Claude API docs.
Calling the API directly is perfect for a quick test or a single app. The moment Fable 5 goes into production across more than one team, you need access control, budgets, and fallbacks, and that is where a gateway comes in.
Direct API access is enough to prototype. Running a premium, token-hungry model like Fable 5 across an organization is a different problem: you have to control who can use it, cap spend, handle the safeguard fallbacks consistently, and keep one view of cost across providers. A gateway sits between your apps and the model and handles all of that.
How enterprises are actually using it, and why a gateway is better
In practice that means a platform team can turn Fable 5 on for the whole company in minutes, with spend controls and fallbacks already in place, instead of each team wiring up the raw API and hoping the bill stays sane.
Step 1: Add Claude Fable 5 to your gateway
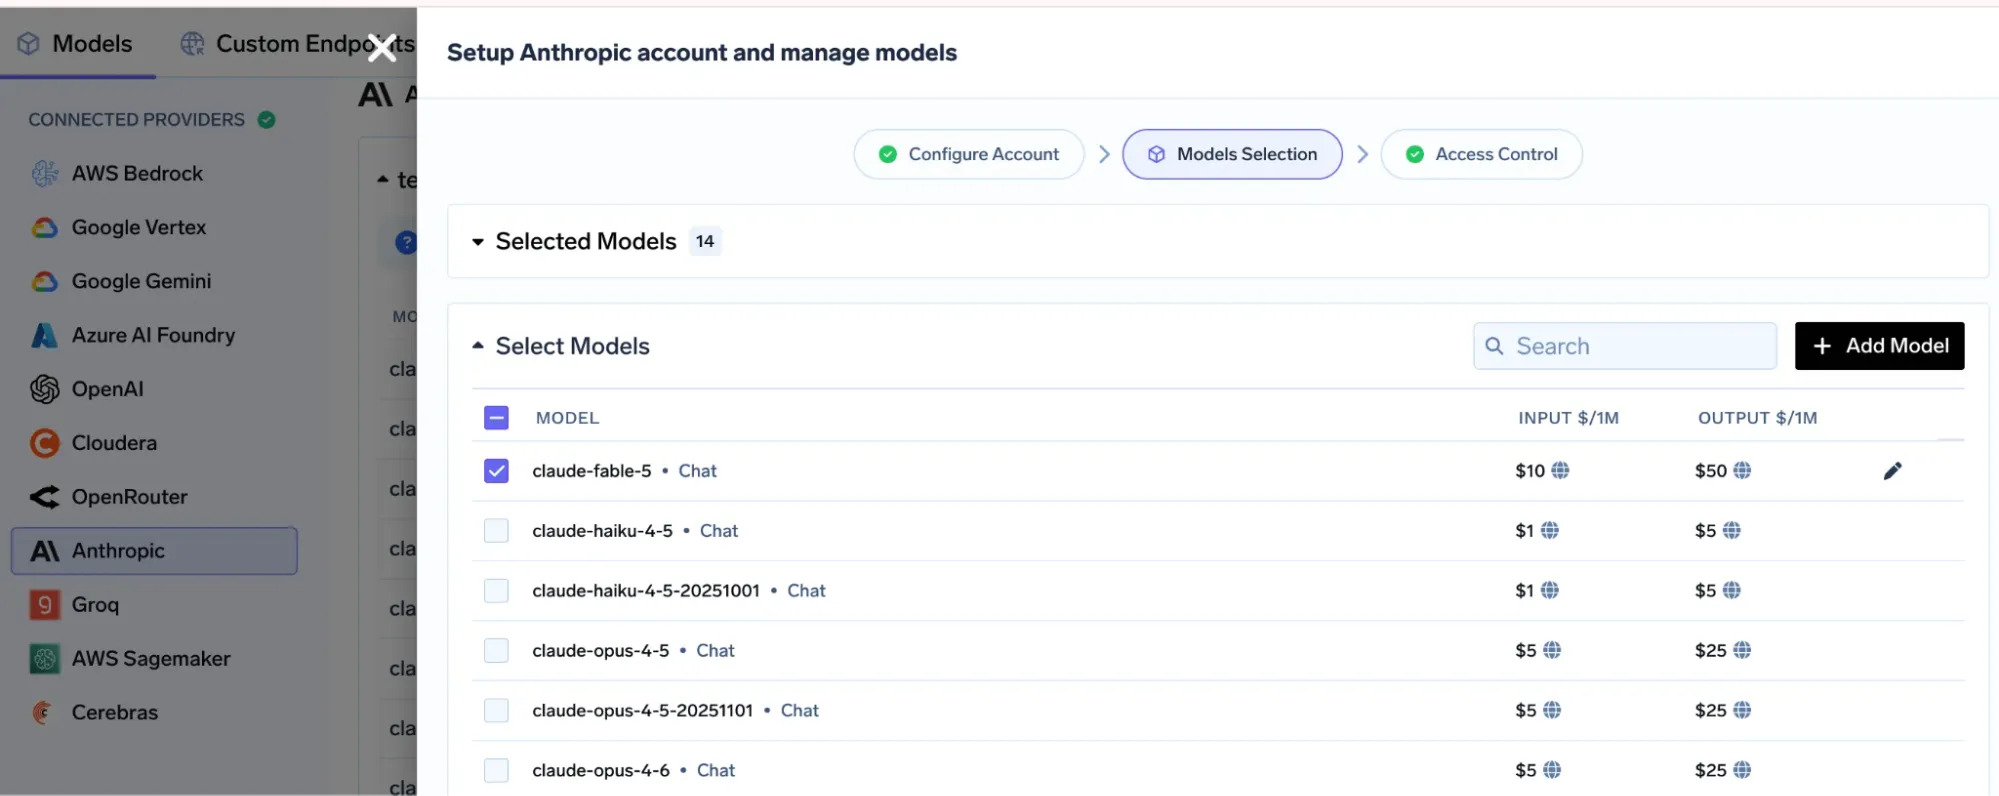
In the TrueFoundry gateway, open your connected Anthropic provider, search for claude-fable-5 on the Models Selection screen, enable it (its $10 / $50 pricing is shown inline), and use Access Control to decide which teams and virtual keys can call it.
Step 2: Call it with the auto-generated snippet
Open the Playground, pick claude-fable-5, and copy the ready-made Usage code snippet. TrueFoundry generates it for OpenAI, LangChain, Node.js, cURL, LlamaIndex, and more, in both streaming and non-streaming modes.
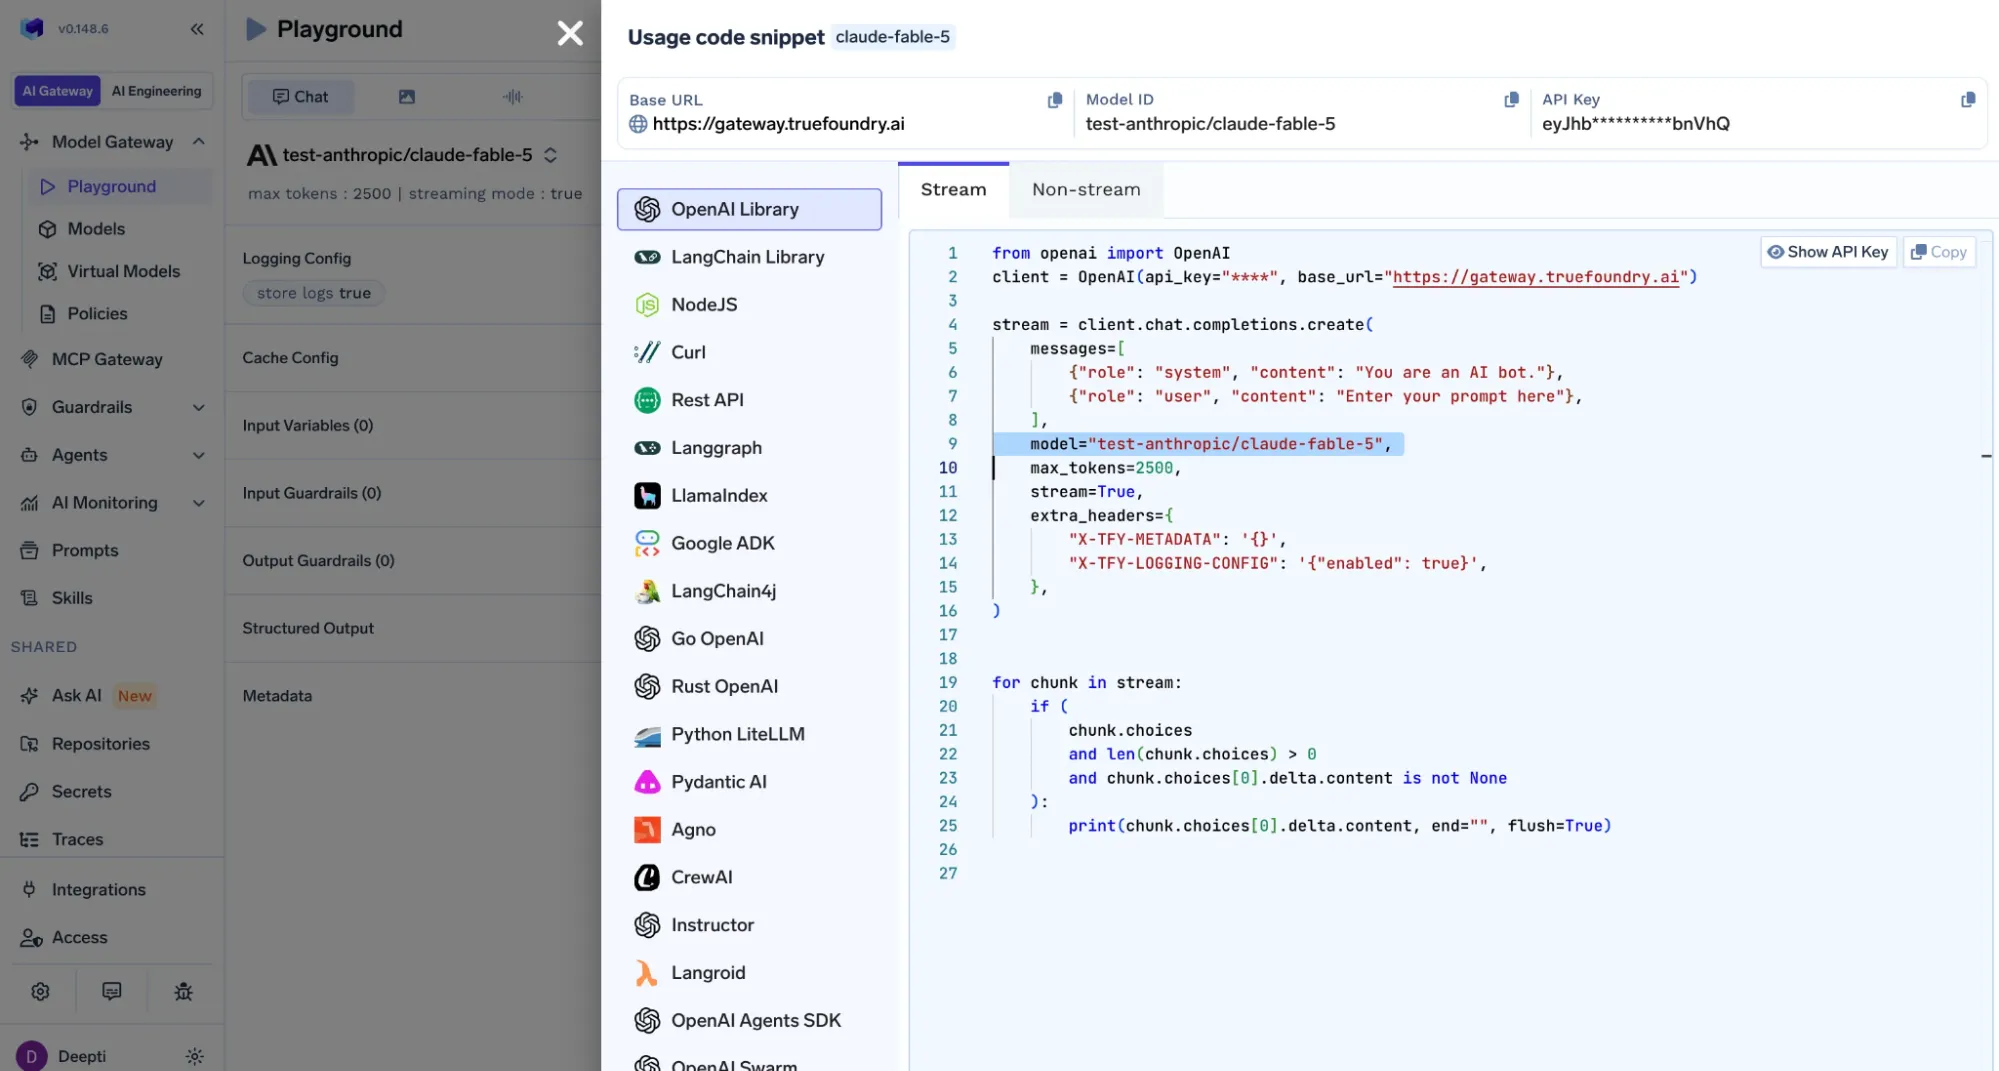
The win: switching between Fable 5, Opus 4.8, GPT-5.5, or any other model is a one-line change, and every call is governed, logged, and observable. Add the X-TFY-LOGGING-CONFIG and X-TFY-METADATA headers to tag and track spend per team or feature.
Claude Fable makes the most sense when you have a task that is difficult, time-consuming, or requires several steps to complete. It is built for work where a quick answer is not enough and the model needs to reason through a problem, use tools, and keep track of context along the way.
You could use Fable for a large software migration, a complex coding project, deep research, detailed document analysis, or an agentic workflow that runs through multiple stages. It can also be useful when you need to work with a large amount of information at once, such as a large codebase or a collection of documents.
But you don't need Fable for every task. If you are writing a short email, summarising a few paragraphs, answering a simple question, or processing a large volume of routine requests, a smaller and cheaper Claude model may be enough. Paying for a more capable model does not automatically make a simple task better.
The easiest way to think about it is to match the model to the task. Use Fable when its stronger reasoning and ability to handle longer workflows can save you time or improve the result. For simpler work, a less expensive model can usually do the job without the additional cost.
If you are choosing a model for a new project, also consider Claude Fable 5.1, which is the newer version of Fable 5. It is the version to evaluate for new long-running coding, research, and other complex workloads.
Ready to put Fable 5 into production with cost controls and fallbacks from day one? Try Claude Fable 5 on the TrueFoundry AI Gateway. Book a demo.
TrueFoundry AI Gateway delivers ~3–4 ms latency, handles 350+ RPS on 1 vCPU, scales horizontally with ease, and is production-ready, while LiteLLM suffers from high latency, struggles beyond moderate RPS, lacks built-in scaling, and is best for light or prototype workloads.




The original Claude Fable 5 API model used claude-fable-5. The current version is Claude Fable 5.1, with the API model ID claude-fable-5-1. It is available through the Claude API and supported cloud platforms, including Amazon Bedrock and Google Cloud.
Claude Fable 5.1 costs $10 per million input tokens and $50 per million output tokens. Five-minute cache writes cost $12.50/MTok, one-hour cache writes cost $20/MTok, while cache reads cost $0.25/MTok. Batch processing offers 50% lower input and output pricing.
Claude Fable 5.1 has a 1-million-token context window and supports up to 128,000 output tokens. It accepts text and image inputs and produces text output. The model also uses adaptive thinking, allowing it to adjust reasoning effort for more demanding tasks.
There is no single benchmark that establishes one model as better for every task. Anthropic's current evaluations compare Fable 5.1 with competing models across coding, reasoning, research, and knowledge work. Results vary by benchmark, so testing both on your workload provides a more useful comparison.
Fable 5 and Mythos 5 share the same underlying model, but have different safeguards and access requirements. The current versions are Fable 5.1 and Mythos 5.1. Fable is generally available, while Mythos is restricted to vetted organisations through trusted-access programmes.
A Fable request can be handled by another Claude model when safety restrictions prevent Fable from completing it. Anthropic supports fallback mechanisms that can retry refused requests on permitted models, including Opus. Therefore, receiving an Opus response does not necessarily mean Fable was unavailable.
You can use Claude Fable through the Claude API, supported cloud platforms, or compatible Anthropic products. For new projects, use the current `claude-fable-5-1` model ID. Choose Fable when your workload needs extended reasoning, large context, or long-running agentic workflows.
You may access Claude Fable through eligible Claude plans, but availability and usage limits depend on your plan and Anthropic's current terms. API usage is separately billed based on tokens. Check Anthropic's current pricing and plan details before relying on free access.
No model can be guaranteed completely resistant to jailbreak attempts. Anthropic continuously evaluates and improves Fable's safeguards against attempts to bypass its safety controls. Avoid treating individual jailbreak demonstrations as evidence of a permanent vulnerability, since model behaviour and safeguards can change over time.
Yes. Fable 5.1 can be used for demanding coding and agentic software-development workflows. It is particularly suited to complex coding tasks that require extended reasoning, tool use, and multiple steps. Availability and model-selection options can depend on your Claude Code setup and plan.
Claude Fable 5.1 is the newer version of Fable 5. It keeps the 1-million-token context window while improving long-running agentic coding, research, and document workflows. It also supports up to 128,000 output tokens and updated caching economics, making it the current version.



The latest news, articles, and resources sent to your inbox